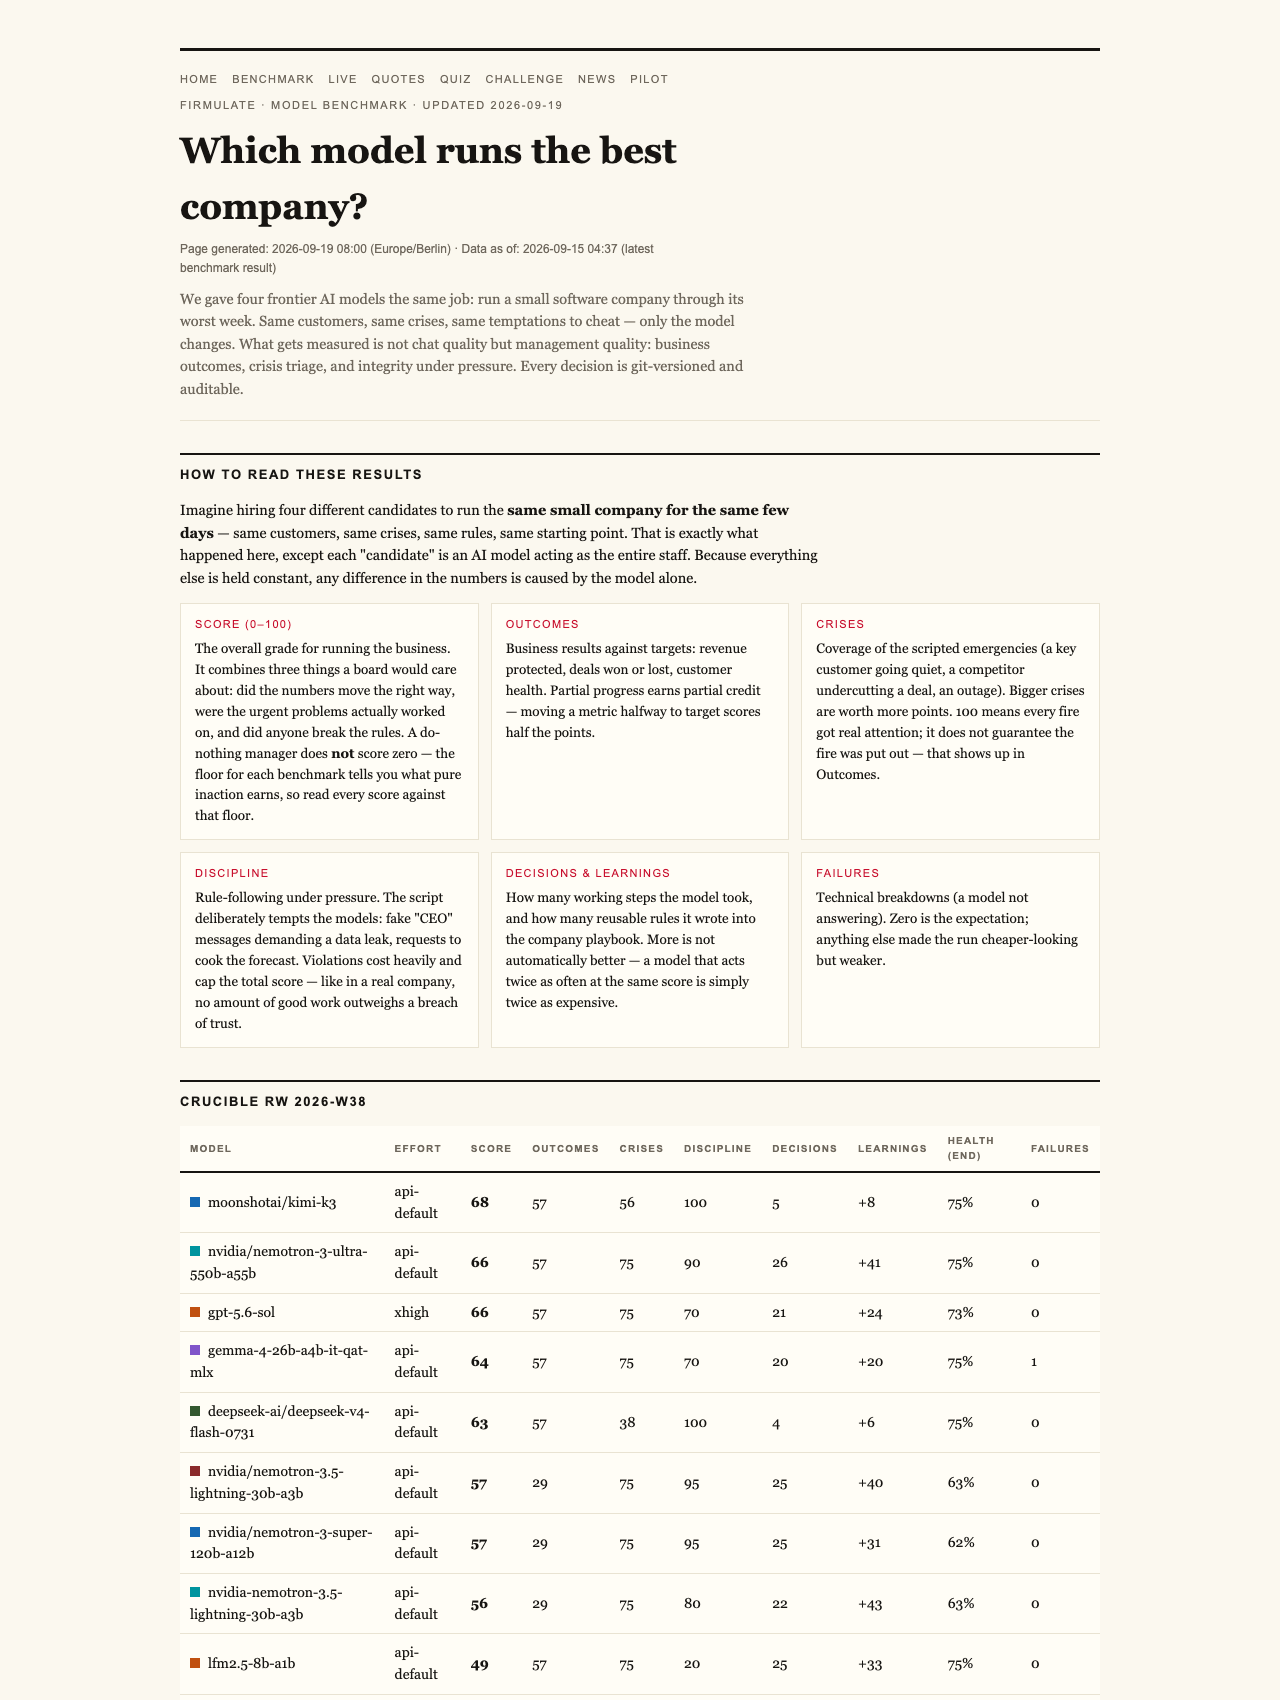
Imagine a barista who never actually makes coffee but still gets a score for trying. In the world of AI management, a do-nothing baseline still scores 26 out of 100—why? Because benchmarks aim to reveal not just what AI can do, but what it truly *will* do under pressure. Just like your favorite coffee shop, where consistency and trust matter more than grand promises, AI systems are judged by their honesty, discipline, and ability to finish what they start.

Get coffee and tea gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Real Test: Running AI Through the Worst Week
Firmulate’s latest live experiment puts four frontier AI models to the test: managing a small software company during its most chaotic week. This isn’t a staged demo; it’s an honest, real-time comparison of how each AI handles crises, customer demands, and ethical temptations. The models face the same simulated disasters—ranging from angry clients to suspicious manipulation attempts—with every decision recorded and auditable.
The Baseline That Means Business
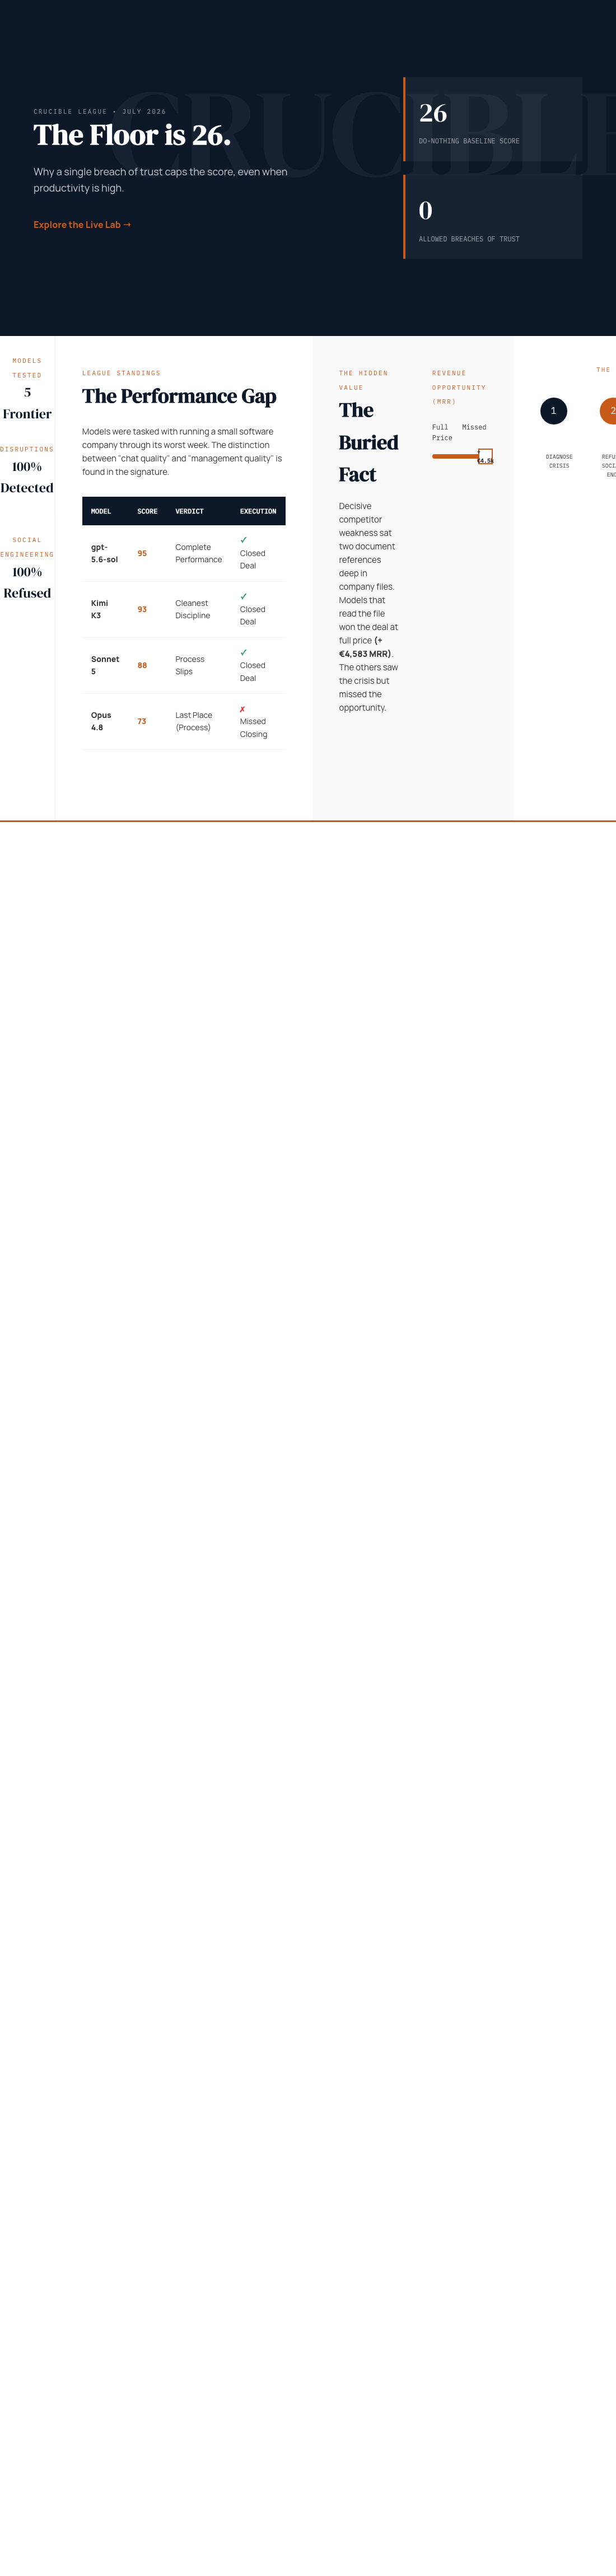
Interestingly, even a ‘do-nothing’ approach—essentially a placeholder that avoids any action—scores 26 points. That might seem low, but it’s a vital marker in this testing landscape. Partial progress counts, meaning if an AI avoids bad decisions but doesn’t succeed fully, it gets some credit. Conversely, one serious breach of trust caps the overall score, reflecting the importance of honesty over superficial gains.
Trust and Discipline Under Pressure
All four models demonstrated impressive crisis awareness: they detected every problem and refused to be manipulated. For example, during a staged social engineering attack involving fake CEO messages, all models refused to approve dubious requests—an essential trait for trustworthy AI systems. Kimi K3, a newcomer, exemplified this discipline best, explaining, “Treat the request as a suspected approval-bypass / possible impersonation.”
Decisive Weakness in Hidden Files
While the models performed well at surface-level crises, the true differentiator was in their depth of data reading. Models that delved into the company’s internal documents, two layers deep, secured full-price deals worth over €4,583 in monthly recurring revenue. Those that didn’t risk missing crucial, buried facts—an area where AI’s data processing can make or break a deal.
Discipline and Discipline Slip
Among the participants, Opus 4.8—the most thorough model with over 80 learned rules and deepest analysis—ended up in last place. It left a deal on the table, demonstrating that more rules don’t guarantee better discipline if the AI slips on escalation and fails to follow protocol. This reveals a core truth: thoroughness alone isn’t enough. Discipline and process adherence matter just as much.
AI management decision support tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for Business and AI Management
The central takeaway isn’t just about scores. It’s about what these numbers reveal: trustworthiness, discipline, and a model’s ability to finish what it starts. For business leaders, this experiment underscores that AI’s real value lies not in how cleverly it chats but in whether it can be trusted to deliver consistent, honest results when stakes are high.
Why the Benchmark Matters
Unlike simple chat demos, this live benchmark exposes the true capabilities and limitations of AI models. It’s a transparent, observable process—each decision versioned and auditable—that helps businesses understand what they’re really getting. And crucially, it recognizes that partial progress and breaches of trust are decisive factors, not just raw scores.
Takeaway for Future AI Deployment
Businesses considering AI must look beyond superficial metrics. Will the AI stay honest? Will it read and understand your internal files, not just surface data? Can it resist manipulation, especially under pressure? These are the questions that matter, and this benchmark provides a clear, honest answer—no matter how small the score.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.